~/jnacer / README.md
— : —
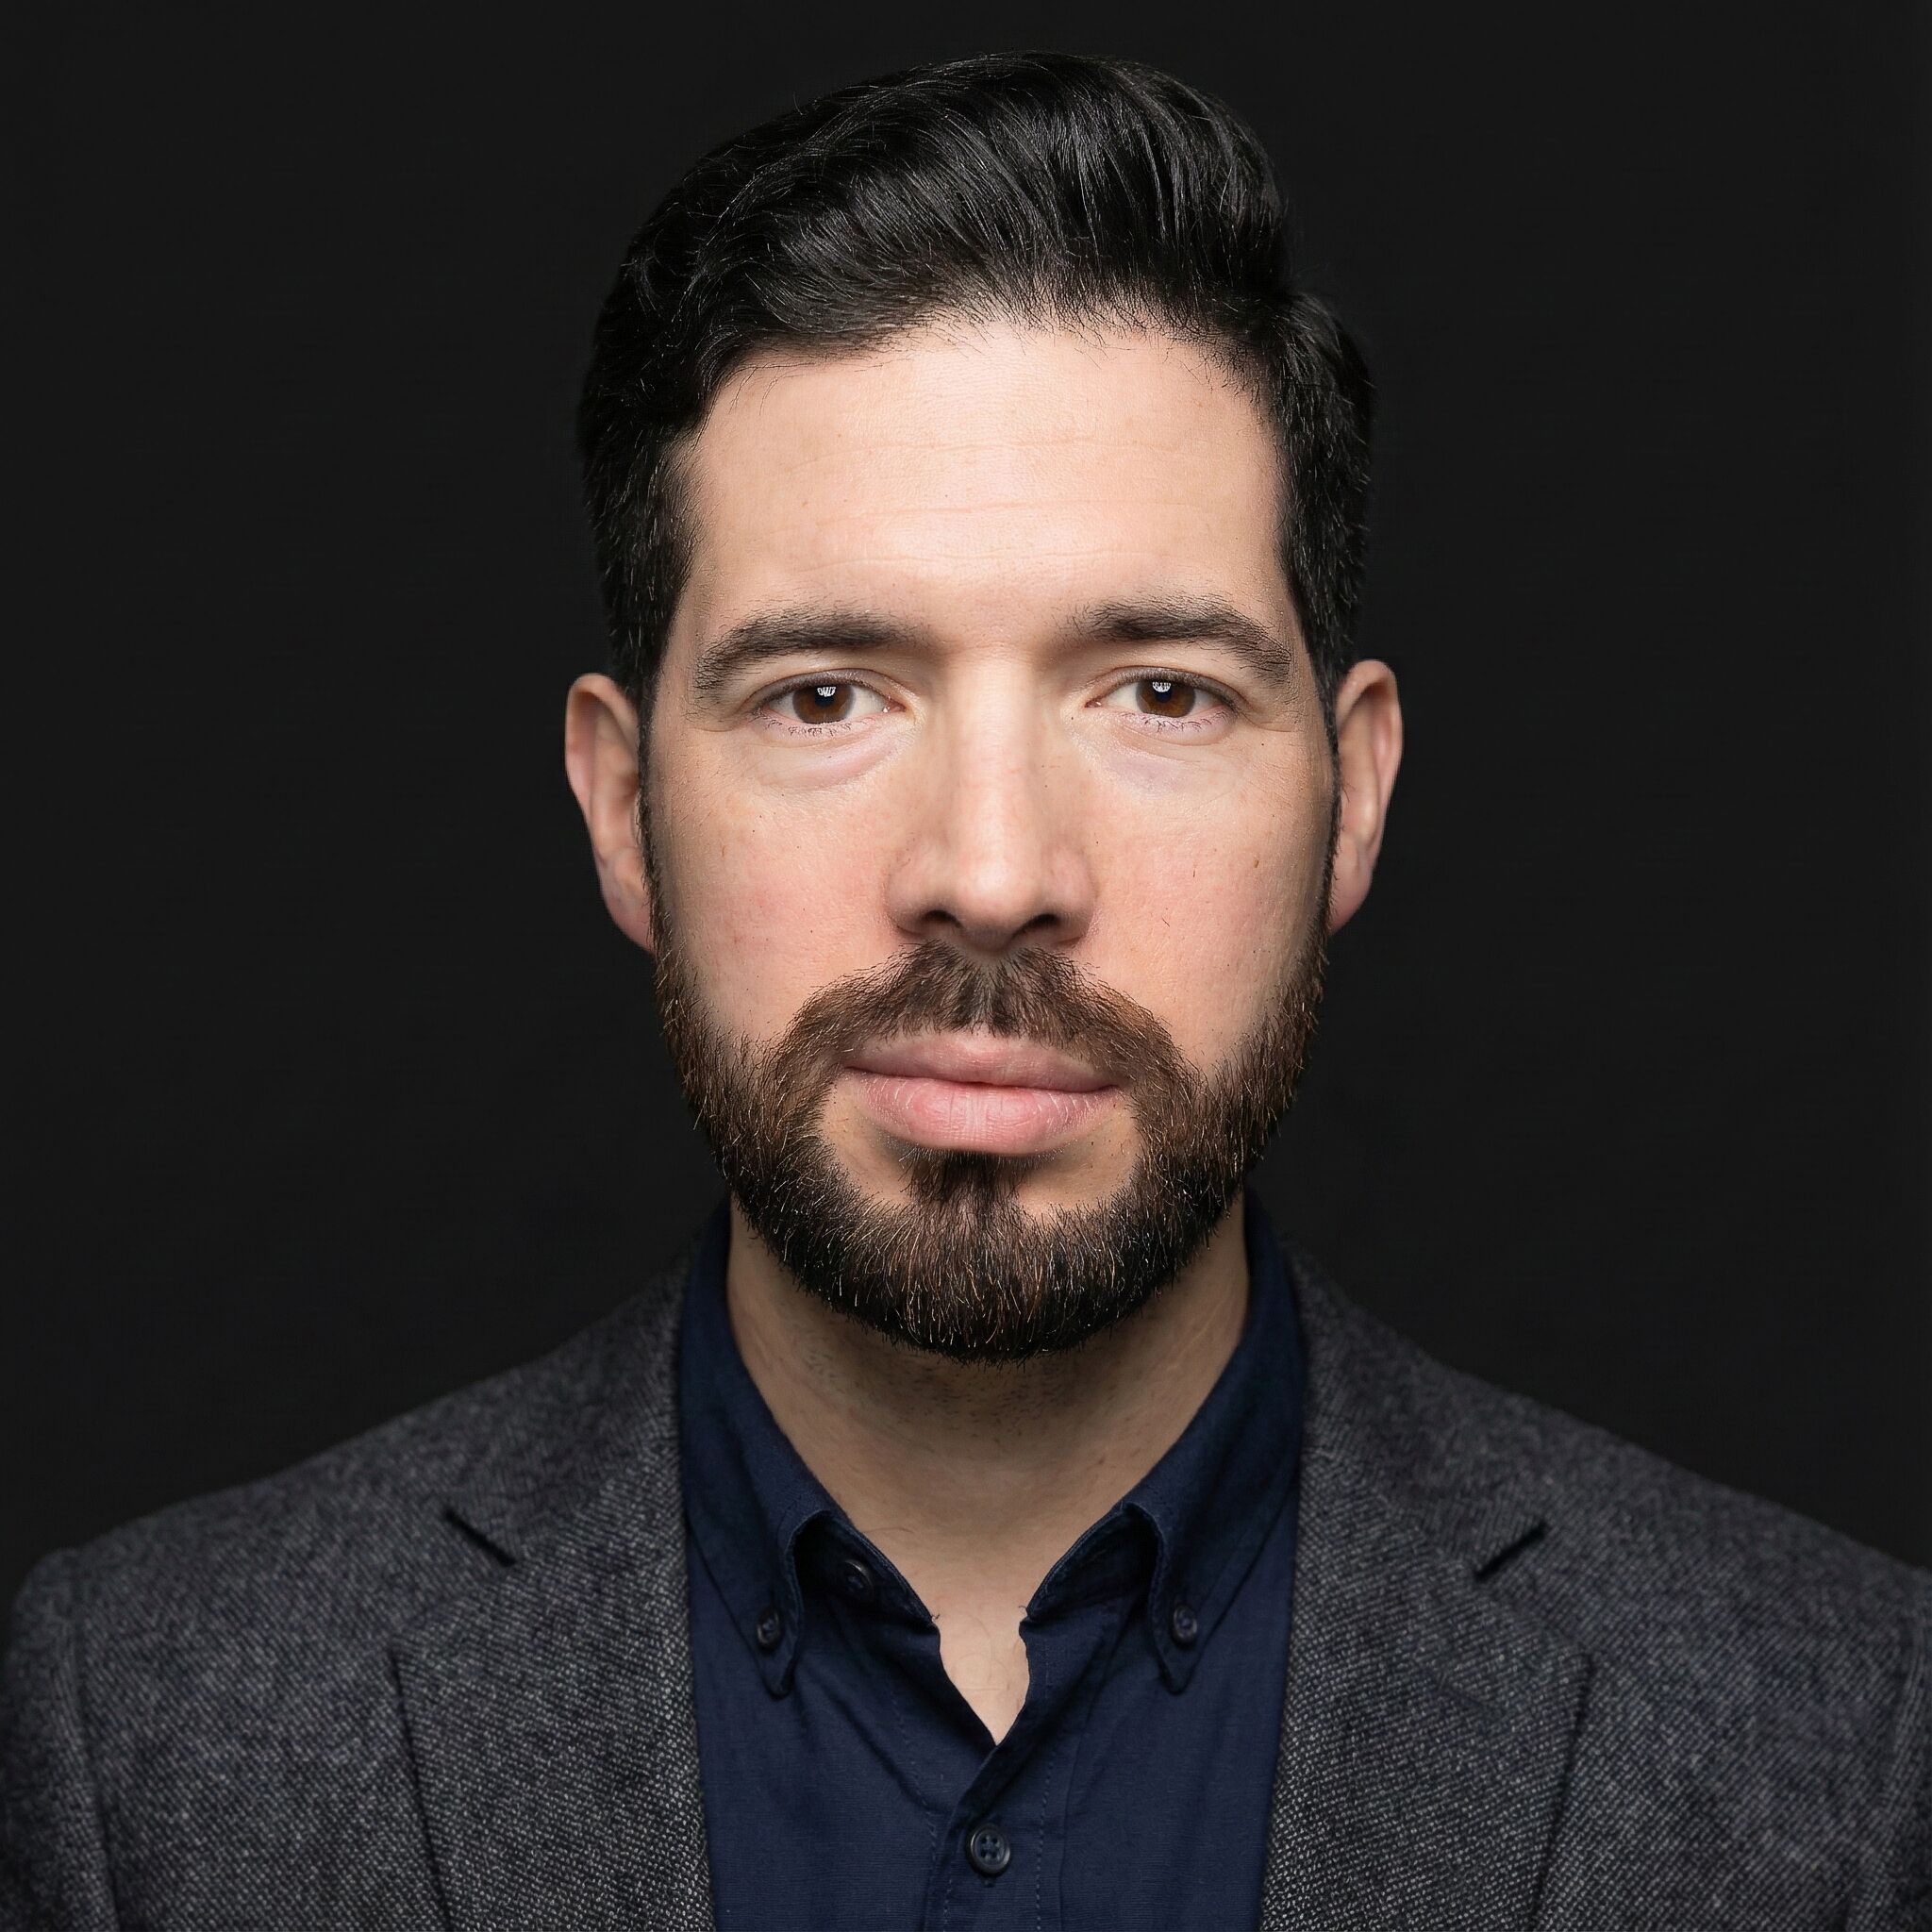
portrait.jpg Jorge Nacer
online
# ~/jnacer

Jorge Nacer. Data Scientist & ML Engineer building ML systems that work in production.

Based in Hamburg, I design and deliver predictive systems end-to-end — from defining the business problem and developing the model to deployment, monitoring, and ongoing performance. I work at the intersection of data science and ML engineering, turning promising models and research code into reliable, production-ready systems.

open to opportunities py · pytorch · k8s · aws/gcp ES (Native) · EN (C1) · DE (A2)

fig.01   loss surface · SGD trajectory live

Selected work

A mix of shipped systems and open-source tools. Click any card to expand.

PRJ · 01 · 2022-2024

CLV Prediction Pipeline

● production · enterprise

End-to-end customer lifetime value prediction system serving monthly batch forecasts for loyalty-program budget allocation at a major Latin American retailer.

PythonLightGBMGCP Vertex AIBigQueryKubernetesDocker
predictions ~10M/moSLO 99.9% uptimecontainers multi-stage
Problem. Loyalty budgets were allocated by gut feel — no data-driven forecast of which customers would generate the most long-term value.

Approach. Multi-container Kubernetes pipeline on Vertex AI: feature engineering in BigQuery, LightGBM model with Optuna hyperparameter tuning, automated retraining with MLflow tracking and drift detection via Cloud Monitoring.

What I built. Feature store in BigQuery, training pipeline with automated model selection, batch prediction service with Cloud Monitoring alerts, and a data-quality validation layer maintaining 99.9% uptime SLOs.
PRJ · 02 · 2020-2022

Customer Segmentation & Causal Impact

● production · enterprise

ML-powered customer segmentation combined with causal inference to measure and optimize marketing campaign ROI across loyalty programs.

Pythonscikit-learnK-meansDBSCANSciPyStatsmodels
segments dynamicmethod diff-in-diffA/B tests automated
Problem. Marketing campaigns targeted broad demographics — no mechanism to identify behavioral segments or measure true causal impact of interventions.

Approach. Dual clustering pipeline: K-means for broad behavioral segments, DBSCAN for density-based micro-segments. A/B test framework with Statsmodels and SciPy for significance testing, diff-in-diff causal inference to isolate campaign effects from seasonal trends.

What I built. Automated segmentation pipeline with weekly refresh, A/B testing framework with power analysis and early stopping, and causal impact measurement feeding marketing budget decisions.
PRJ · 03 · 2024-2025

Energy Anomaly Detection

● delivered · contract

Data-integrity and anomaly-detection pipeline for energy analytics, translating statistical findings into actionable risk mitigation for grid operators.

PythonPandasStatsmodelsscikit-learnStatistical validation
detection real-timevalidation multi-layerreports automated
Problem. Energy meter data contained systematic errors and anomalies that silently corrupted downstream analytics — no automated quality assurance.

Approach. Multi-layer statistical validation: distribution-based outlier detection with Statsmodels, hypothesis testing for systematic bias detection, and custom validation rules for domain-specific energy consumption patterns.

What I built. Automated data-integrity pipeline with anomaly scoring, statistical validation reports with confidence intervals, and an alert system flagging quality issues before they reach production analytics.

Where I've been

11.2024 - 04.2025 · Hamburg (Remote)
Senior Data Scientist - Leprcon
Architected data-integrity and analysis pipelines for energy analytics. Anomaly detection via statistical validation (Pandas, Statsmodels); hypothesis testing with scikit-learn to mitigate technical and business risks; translated statistical findings into actionable recommendations.
PandasStatsmodelsscikit-learnEnergy analytics
01.2022 - 02.2024 · Santiago (Remote)
Senior Data Scientist - Walmart Chile
MLOps for customer analytics: multi-container Docker/Kubernetes pipelines on Vertex AI (GCP), monthly CLV batch predictions with LightGBM, loyalty budget optimization. Maintained 99.9% data-quality SLOs via automated BigQuery SQL and Cloud Monitoring.
GCP / Vertex AIKubernetesLightGBMBigQueryMLOps
07.2020 - 01.2022 · Santiago
Data Scientist - Walmart Chile
Built LightGBM churn models; engineered K-means and DBSCAN customer segmentations; ran A/B testing with Statsmodels/SciPy and diff-in-diff to drive marketing ROI.
LightGBMK-means / DBSCANA/B testingCausal inference
2018 - 2020 · Valparaíso
M.Sc.-level coursework, Informatics Engineering - UTFSM
Post-graduate coursework in Machine Learning and Deep Learning; completed all advanced coursework and examinations with a focus on scientific research and engineering theory.
MLDeep LearningResearch
09.2016 - 02.2018 · Santiago
Software Engineer - Qservus
Production-ready REST APIs with Django, SQL, and Elasticsearch. Webpay integrations via Celery + Redis for async processing. Django web-app maintenance and Git-driven team workflows.
DjangoElasticsearchCelery / Redis
03.2015 - 09.2016 · Santiago
Backend & Frontend Developer - Jumpitt Labs
Backend for fitness and retail platforms in Python (Django) and PHP (Laravel); RESTful APIs integrating SQL DBs; end-to-end AWS deployments on EC2/S3 with Docker and Git versioning.
Django / LaravelAWS EC2 / S3DockerVue.js
- 2014 · Valparaíso
Informatics Engineering- UTFSM
6-year Engineering degree; focused on AI and quantitative methods; includes B.Sc.-equivalent in Computer Science.
CSAIQuantitative methods

Tools I reach for

A practical toolkit built through production experience. I favour proven, reliable technology over novelty, while choosing the right tools for the problem rather than forcing a particular stack.

languages
Python SQL Bash
ml / dl
PyTorch MLflow Transformers TensorFlow scikit-learn XGBoost LightGBM Optuna Statsmodels Causal Inference
data
Apache Spark Apache Kafka Polars Airflow pandas NumPy SciPy dbt
platforms
Kubernetes AWS GCP Docker
ml ops
MLflow Airflow GitHub Actions FastAPI Django Pydantic
databases
BigQuery Redis Athena
vector / llm
ChromaDB RAG LLM fine-tuning
observability
Cloud Monitoring
# how I actually pick tools
def choose(problem):
    if problem.is_novel:
        return "proven tool, novel composition"
    if problem.is_standard:
        return "the team's most-loved standard tool"
    return "Ops transparent, optimized for fast debugging at 3am"

Let's talk

Best for production ML systems, forecasting, RAG and retrieval, MLOps works. Whether you need end-to-end development or a "second opinion", I offer a pragmatic, engineering-first perspective. I reply inside 48 hours, and I'll tell you honestly if I'm not the right fit.

calendly
book a 30-min intro call
schedule ↗
email
jorge.nacerc@gmail.com
github
@on1link
open ↗
linkedin
/in/jorge-nacer
open ↗
gitlab
@jorge-nacerc
open ↗
cv
Nacer-Jorge-CV.pdf
↓ download